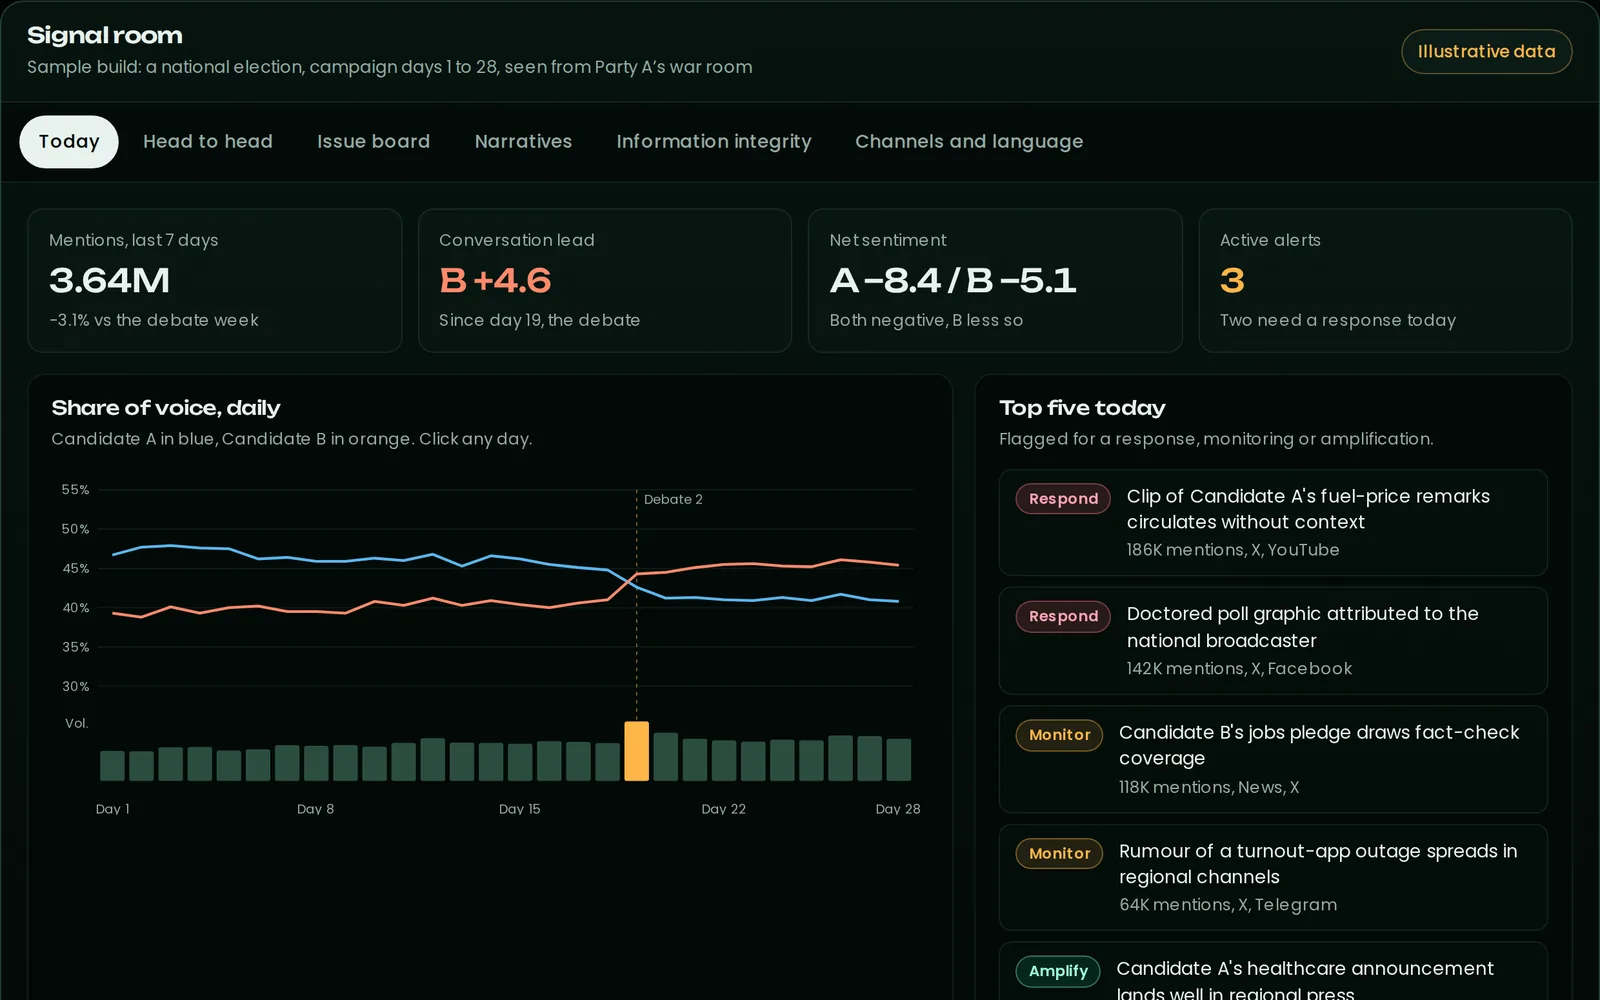
We stop the build when the data is wrong.
On one government build, the local-language share of the corpus came back at 1.6%. The brief needed 45%. Charts on that data would have shown a mostly English, mostly national conversation as if it were the region's mood.
So the build stopped there, with the evidence written up, instead of thirteen pages of confident, wrong numbers. When the dashboard was built, the gap sat on its own panel, not in a footnote. Every figure we ship carries one of three labels.
- Measured
- Counted directly from the licensed corpus.
- Assessed
- An analyst's reading, with its confidence stated.
- Data gap
- What the data can't see. Said out loud, never filled in.